
ASRock Intel Arc Pro B60 Creator 24GB
3.9Editor score
24GB GDDR6 VRAM
PCIe 5.0 support
Optimized for Linux multi-GPU
This guide compares the top GPUs for Llm workloads, evaluating memory capacity, architecture, and performance to help you choose the right hardware for AI
Finding the right GPU for Llm workloads requires balancing memory capacity, architecture efficiency, and thermal performance. This guide explores the latest graphics cards designed to handle complex AI inference and training tasks effectively.
We evaluated ten top-rated products based on VRAM size, bus width, cooling solutions, and compatibility with modern AI frameworks. Each entry includes detailed specifications and real-world performance insights for developers and researchers.
Every pick highlights key strengths, trade-offs, and ideal use cases to streamline your decision-making process. Please note that availability and pricing can fluctuate frequently, so verify current listings before purchasing your new hardware.
3.9Editor score

4.6Editor score

4.3Editor score
The following table provides a side-by-side comparison of all ten selected GPUs, highlighting their core specifications, memory configurations, and key architectural features to assist your evaluation.




The GIGABYTE GeForce RTX 5080 Gaming OC 16G stands out as a top-tier option for developers running local LLM workloads. Its NVIDIA Blackwell architecture and 16GB GDDR7 memory provide a robust foundation for efficient inference and moderate fine-tuning tasks.
We may earn a commission when you buy through this link, at no additional cost to you.
This card excels in thermal management thanks to the WINDFORCE cooling system, which ensures sustained performance during extended AI sessions. The PCIe 5.0 interface guarantees maximum bandwidth, reducing bottlenecks when transferring large model weights from system memory.
While 16GB VRAM is ample for many open-source models, it may limit context windows for the largest enterprise-grade LLMs. Additionally, the price point reflects its premium positioning, making it a significant investment for solo researchers or small teams.
For professionals seeking a balance of speed and reliability without enterprise-level costs, this GPU offers exceptional value. It is highly recommended for those prioritizing inference speed and thermal stability in a desktop workstation environment.
The GDDR7 memory delivers significantly higher bandwidth compared to previous generations, allowing faster data access during token generation.
Multiple fans and a large heatsink maintain low temperatures, preventing thermal throttling during intensive AI workloads.
We may earn a commission when you buy through this link, at no additional cost to you.
The ASRock Intel Arc Pro B60 Creator 24GB offers an attractive entry point for those needing substantial VRAM without breaking the bank. Its 24GB GDDR6 memory allows loading larger models than many competitors at this price point.
We may earn a commission when you buy through this link, at no additional cost to you.
Intel's Xe2-HPG architecture includes dedicated AI accelerators that boost inference performance. The card is optimized for Linux multi-GPU deployments, making it ideal for budget-conscious clusters aimed at scaling inference workloads across multiple units.
Drivers and tooling are improving but may lack the maturity found in NVIDIA CUDA ecosystems. Users might encounter occasional compatibility hurdles with certain libraries, requiring more hands-on configuration compared to established alternatives.
Despite these minor software challenges, the hardware value proposition is strong. It is best suited for teams comfortable with open-source stacks who prioritize memory capacity over absolute peak raw compute performance.
The 24GB VRAM allows running larger context windows or multiple smaller models simultaneously on a single card.
Optimized for multi-GPU setups, enabling cost-effective scaling for distributed inference tasks.
We may earn a commission when you buy through this link, at no additional cost to you.
The NVlDlA RTX PRO 6000 Blackwell max-Q Workstation Edition represents the pinnacle of local AI hardware with its staggering 96GB of GDDR7 ECC memory. This capacity removes almost all VRAM bottlenecks for even the largest open-source models.
We may earn a commission when you buy through this link, at no additional cost to you.
Designed for professional workstations, it balances massive memory with a modest 300W power envelope. The 512-bit bus ensures rapid data movement, critical for maintaining high throughput during heavy inference or training sessions.
The premium price tag places this out of reach for most individual developers, but it delivers unmatched capability for labs requiring local hosting without cloud latency. ECC memory ensures data integrity during long-running scientific simulations.
If budget is no constraint and performance is paramount, this card sets the standard. It is the ideal choice for research institutions or enterprise teams needing secure, on-premise AI infrastructure with minimal external dependencies.
With 96GB of VRAM, users can load full parameter LLMs without quantization or offloading compromises.
ECC memory corrects bit errors silently, ensuring accurate computation during critical scientific workloads.
We may earn a commission when you buy through this link, at no additional cost to you.
The ASRock Radeon AI PRO R9700 Creator 32GB targets professional content creators and AI developers with its specialized RDNA 4 architecture. The 32GB GDDR6 memory strikes a solid balance for mid-to-large local model deployments.
We may earn a commission when you buy through this link, at no additional cost to you.
Featuring dedicated AI accelerators and a professional blower cooler, this card excels in multi-GPU workstation configurations where heat exhaust is managed efficiently. The enterprise-grade thermal solution ensures reliability during 24/7 operation.
While AMD software tools are improving, they may not match the breadth of NVIDIA offerings for niche AI libraries. Users should verify driver compatibility with their specific inference frameworks before committing to this hardware.
For organizations already invested in AMD ecosystems or seeking non-NVIDIA alternatives, this GPU offers compelling performance. It is best suited for teams needing reliable compute power with strong thermal management capabilities.
The blower design efficiently moves heat out of the chassis, crucial for dense server rack deployments.
Dedicated accelerators within the RDNA 4 chip speed up common tensor operations used in LLM inference.
We may earn a commission when you buy through this link, at no additional cost to you.
The GIGABYTE Radeon RX 9070 XT Gaming OC 16G brings gaming-grade performance to local AI tasks. Its 16GB GDDR6 memory and PCIe 5.0 interface provide sufficient resources for running various open-source models efficiently.
We may earn a commission when you buy through this link, at no additional cost to you.
With the WINDFORCE cooling system and server-grade thermal gel, this card maintains stable temperatures even under sustained loads. The robust construction ensures longevity for users who need a single card for both creative work and AI testing.
Lacking dedicated AI accelerators found in professional cards, raw inference speeds may lag slightly behind optimized enterprise GPUs. However, for generalist use cases, it delivers a balanced performance profile at a competitive market position.
This option is ideal for enthusiasts or small studios that need versatility. It provides a cost-effective entry point into local LLM experimentation without sacrificing the reliability expected from major hardware brands.
Advanced cooling materials ensure the GPU stays cool during extended inference sessions.
Suitable for both creative rendering and AI tasks, maximizing hardware utility for mixed workloads.
We may earn a commission when you buy through this link, at no additional cost to you.
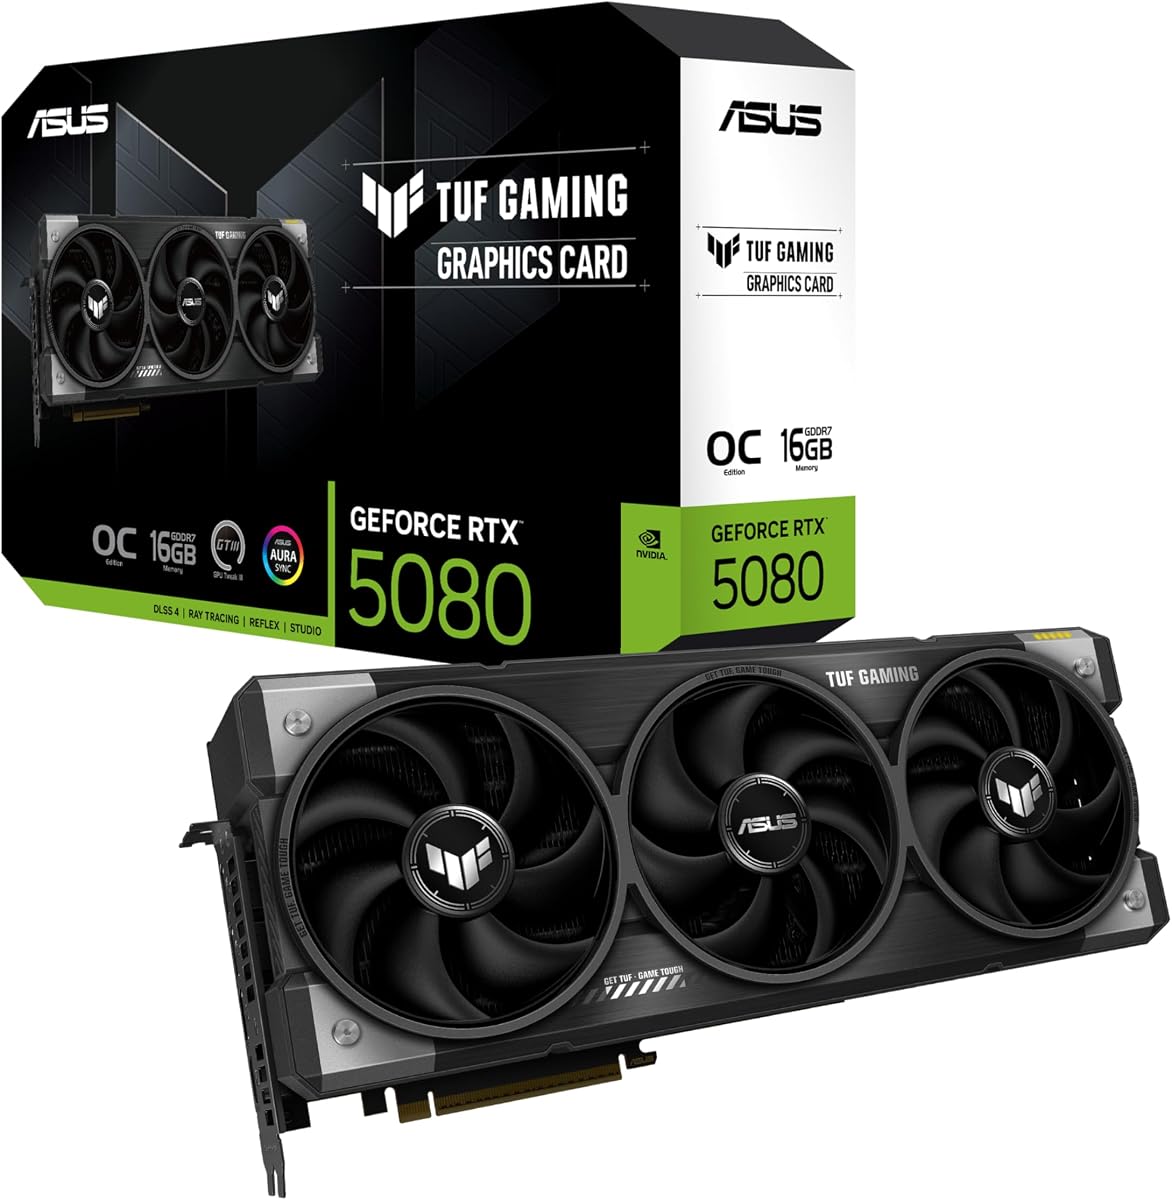
The ASUS TUF Gaming GeForce RTX 5080 16GB combines military-grade components with the latest NVIDIA Blackwell architecture for reliable AI computation. Its 16GB GDDR7 memory supports efficient inference for standard model sizes.
We may earn a commission when you buy through this link, at no additional cost to you.
Features like protective PCB coating and phase-change thermal pads enhance durability and longevity. The Auto-Extreme automated manufacturing process ensures higher reliability, reducing the risk of hardware failure during critical development phases.
The card demands a robust power supply due to its performance capabilities. While durable and powerful, the cost can be prohibitive for some, though the build quality justifies the investment for long-term use.
For users prioritizing hardware reliability and brand trust, this GPU is an excellent choice. It delivers consistent performance that withstands the rigors of professional AI development and heavy creative workloads.
Military-grade components and protective coatings extend the lifespan of the GPU under demanding conditions.
Phase-change pads and Axial-tech fans work together to keep the core cool and stable.
We may earn a commission when you buy through this link, at no additional cost to you.
The ASUS Turbo Radeon AI PRO R9700 32GB is explicitly built for running LLMs locally with its RDNA 4 architecture and 128 AI accelerators. The 32GB VRAM allows handling complex models without immediate offloading.
We may earn a commission when you buy through this link, at no additional cost to you.
Multi-GPU scaling support facilitates dense local AI clusters for training or distributed inference. The diecast shroud and phase-change thermal pad help maintain consistent clocks during long training runs, ensuring stability.
User feedback suggests software optimization is still catching up to the hardware potential. While the specs are impressive, some users report a learning curve when configuring optimal settings for different model architectures.
For teams needing dedicated AI hardware in a compact form factor, this card presents a compelling option. It is best suited for those comfortable tweaking performance settings to maximize its specific AI acceleration features.
With up to 1,531 TOPS for INT4, inference tasks process rapidly on this dedicated AI hardware.
Designed to work well in multi-GPU setups for scaling local AI training efforts.
We may earn a commission when you buy through this link, at no additional cost to you.
The ASUS Dual GeForce RTX 5060 Ti 16GB offers a compact solution for users with smaller workstations needing 16GB VRAM. Its GDDR7 memory provides fast access for local model inference tasks.
We may earn a commission when you buy through this link, at no additional cost to you.
The 2.5-slot design maximizes compatibility with smaller chassis while maintaining effective cooling. With 0dB technology, it operates silently during light tasks, ensuring a quiet environment for focused work or development.
While raw compute power is lower than higher-end models, it handles typical open-source models efficiently. The balance of size, memory, and performance makes it a versatile choice for space-constrained setups.
Ideal for students or professionals with limited desk space, this card provides a powerful entry point into local AI. It delivers sufficient capability for experimentation without requiring a full-sized workstation chassis.
The compact design fits into small cases, allowing powerful AI hardware in limited spaces.
Noise reduction technologies ensure the system remains quiet during standard inference workloads.
We may earn a commission when you buy through this link, at no additional cost to you.
The Tesla L40S 48GB AI HPC Graphics Accelerator is designed primarily for data center environments with its massive 48GB VRAM. It excels at handling large-scale AI workloads and high-performance computing tasks.
We may earn a commission when you buy through this link, at no additional cost to you.
Featuring a blower-style cooling design, it dissipates heat efficiently in rack-mounted configurations. The card focuses purely on compute, lacking display outputs, which makes it ideal for headless server deployments.
While powerful, it requires specific chassis and power setups typical of enterprise server environments. This makes it less suitable for standard desktop users who need display connectivity alongside AI processing capabilities.
For data centers or advanced server clusters needing high memory density without display features, this accelerator is highly effective. It provides robust compute power tailored for specialized, high-throughput AI pipelines.
With 48GB of VRAM, it supports large batches or extensive model parameters locally.
Blower cooling ensures efficient heat removal in tightly packed server rack configurations.
We may earn a commission when you buy through this link, at no additional cost to you.
The NVD RTX PRO 6000 Blackwell Professional Workstation Edition brings top-tier enterprise features with 96GB of GDDR7 ECC memory. Its double-flow-through cooling design supports heavy workloads efficiently under peak power loads.
We may earn a commission when you buy through this link, at no additional cost to you.
Universal MIG technology allows dividing the GPU into multiple isolated instances for concurrent workloads, enhancing utilization and security. PCIe Gen 5 support ensures data transfer speeds match the GPU's processing capabilities.
While the price is significantly higher than consumer options, the specialized features justify it for professional labs. The OEM packaging means bulk purchases are typical, often suited for direct hardware distribution scenarios.
This card is the ultimate choice for institutions requiring maximum isolation, security, and memory capacity. It supports advanced enterprise workflows where reliability, scalability, and performance are critical success factors.
Universal MIG enables multiple users to run separate workloads securely on a single physical GPU.
Double-flow-through design maintains optimal temperatures during sustained high-power professional workloads.
We may earn a commission when you buy through this link, at no additional cost to you.
Selecting the right GPU involves evaluating several technical factors that directly impact your ability to run and scale AI workloads efficiently.
VRAM capacity determines the maximum size of the model you can load entirely on the GPU without swapping to system RAM. Larger models require more VRAM to prevent bottlenecks during inference or fine-tuning operations.
Aim for at least 16GB for most modern open-source models, with 24GB or higher preferred for larger enterprise-scale deployments.
High memory bandwidth ensures rapid data transfer between VRAM and compute cores, crucial for maintaining high inference speeds. This metric depends on memory type and bus width.
Prioritize cards with newer memory standards like GDDR7 and wider bus interfaces to reduce latency during token generation.
Modern architectures like Blackwell, RDNA 4, and Xe2-HPG include dedicated AI accelerators that speed up common tensor operations used in LLMs. Check if the architecture matches your software stack.
Ensure the architecture is well-supported by your preferred inference frameworks to avoid compatibility issues.
AI workloads often run for extended periods, generating significant heat that can cause throttling. Effective cooling systems maintain stable performance over time.
Look for robust cooling solutions like WINDFORCE or blower designs depending on your chassis airflow needs to ensure longevity.
PCIe 5.0 interfaces offer double the bandwidth of PCIe 4.0, facilitating faster data transfer between CPU and GPU memory. This reduces bottlenecks when loading models.
Select cards with PCIe 5.0 support if your motherboard supports it to maximize data throughput.
Scaling across multiple GPUs allows you to run larger models or handle higher request volumes. Verify support for technologies like MIG or Linux multi-GPU configurations.
Ensure the card is optimized for cluster environments if you plan to expand your AI infrastructure later.
Driver maturity and library compatibility can vary significantly between vendors. NVIDIA's CUDA ecosystem is most established, while AMD and Intel options are improving.
Confirm that your development tools and libraries support the chosen GPU's drivers before purchasing.
High-performance cards often demand more wattage from your power supply. Over-provisioning ensures stable operation and prevents system instability.
Verify your PSU capacity matches the GPU's TDP requirements to avoid unexpected shutdowns under load.
Install the latest drivers and ensure your system BIOS supports PCIe 5.0 modes to unlock full bandwidth capabilities for your new GPU.
Configure your inference software to prioritize GPU memory allocation and monitor VRAM usage to prevent out-of-memory errors during training or long sessions.
Regularly clean dust from fans and heatsinks to maintain cooling efficiency, and consider using GPU monitoring tools to track temperatures during prolonged workloads.
At least 16GB is recommended for most open-source models. Larger models with more parameters may require 24GB or 32GB to avoid offloading to system RAM.
Yes, gaming GPUs like RTX series support AI workloads well. However, professional cards often offer better reliability and multi-GPU support.
It provides significant bandwidth benefits, especially for large models. PCIe 4.0 still works but may bottleneck data transfer speeds in some cases.
Support is improving with frameworks like ROCm and OpenVINO. However, NVIDIA CUDA remains the most widely supported ecosystem for AI development.
More VRAM allows for longer context windows without offloading. Each additional token consumes memory proportional to model size and precision.
ECC memory corrects bit errors during calculations. It is critical for scientific accuracy but less vital for casual LLM inference tasks.
The ideal GPU depends on your specific model sizes and budget constraints. The GIGABYTE RTX 5080 offers a strong balance, while the RTX PRO 6000 provides unmatched capacity for enterprise needs.
Prioritize VRAM capacity and memory bandwidth above all else when selecting hardware. These factors directly determine which models you can run locally without sacrificing performance.
Always verify current compatibility and availability before making a purchase decision as hardware specifications and software support evolve rapidly in this field.